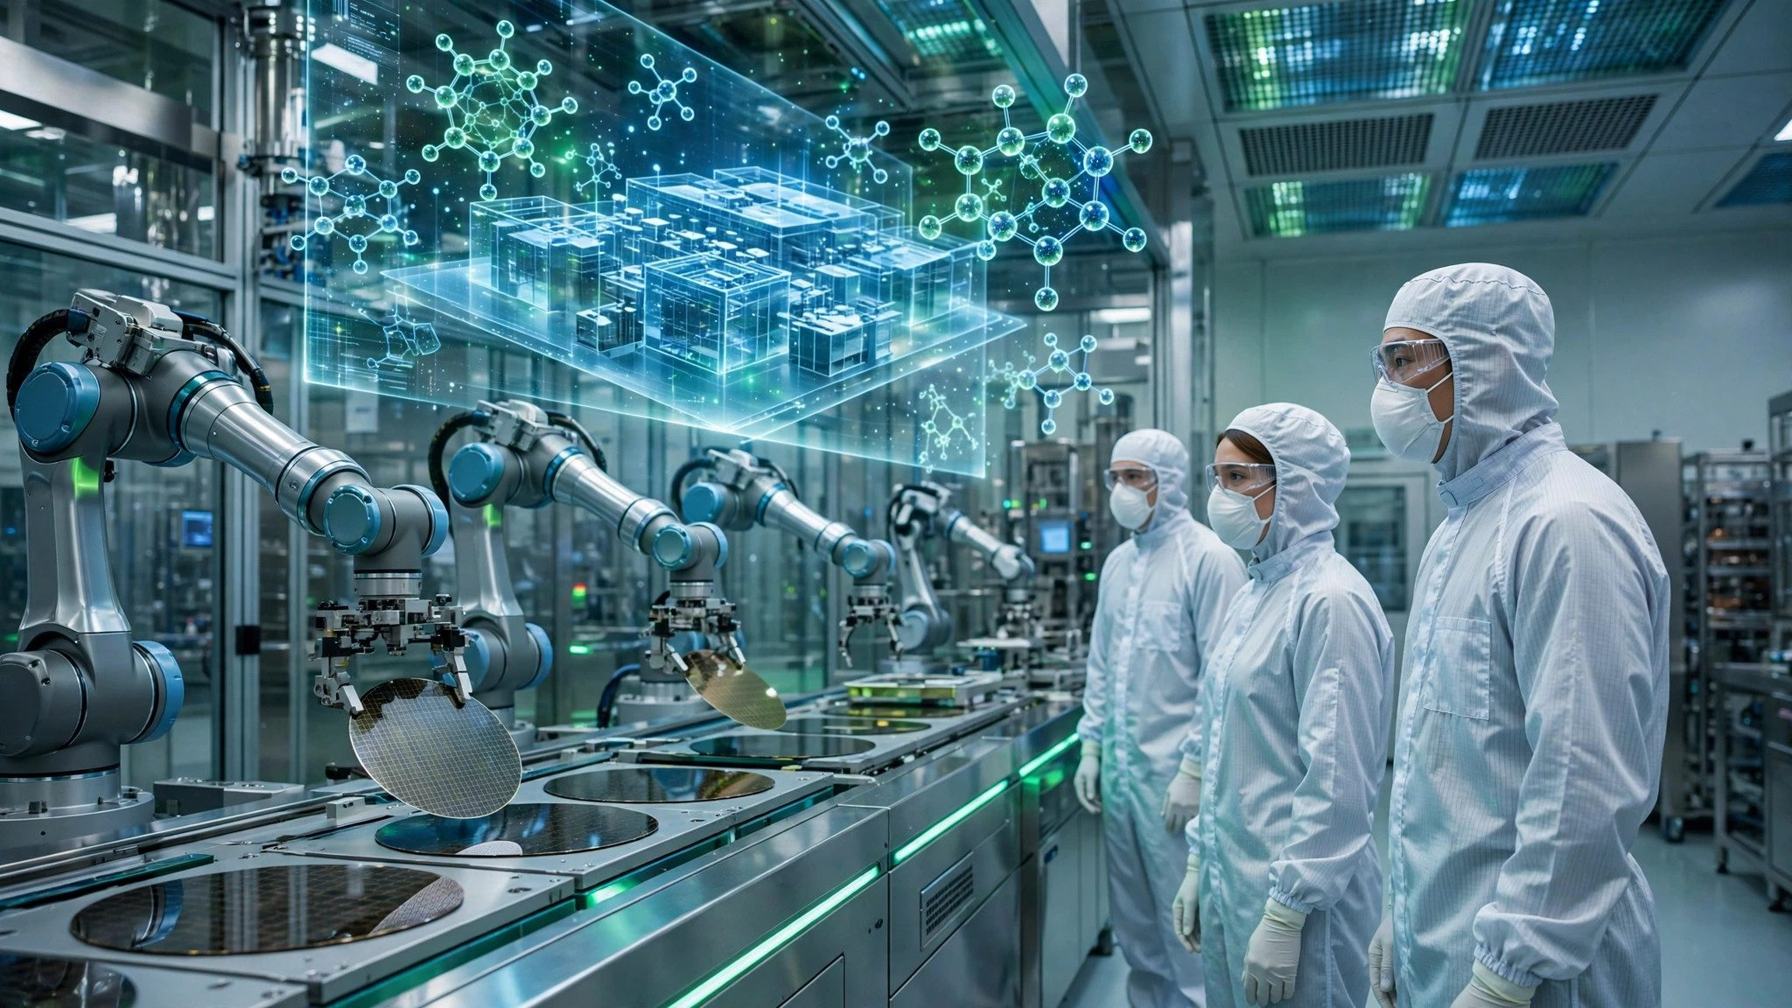
NVIDIA used SEMICON West on October 14, 2026 to announce cuPotential, a new library in its CUDA-X family, alongside word that Applied Materials, Cadence, KLA, Lam Research, Siemens, and Synopsys are adopting NVIDIA's accelerated computing and AI stack across chip design, manufacturing, and testing. The substance is not one more software library. It is NVIDIA filling in the lowest layer of its "AI-defined fab" vision: letting agents work out how materials behave at atomic scale in simulation, before any conclusion is allowed near a production line.
cuPotential targets the slowest link in the simulation chain
Understanding how atoms and molecules interact is the starting point for modeling semiconductor materials and processes, and those calculations are notoriously slow even in software already optimized for GPUs. cuPotential provides specialized GPU-accelerated functions that developers can add to existing tools, so AI agents can run, evaluate, and iterate on molecular simulations directly. In early-access testing, it accelerated already GPU-optimized workflows by a further 2-3x. Synopsys is among the early adopters, using it to speed up materials simulation. Its role is deliberately unglamorous: not a consumer product, but shared low-level tooling for engineers and agents, meant to keep trial and error inside the computer.
A string of speedups adds up to a factory-level argument
The partner numbers in the same release are dense. In materials and device simulation, Synopsys reports a potential 30x speedup with cuEST in QuantumATK and 12x with cuDSS on S-Device benchmarks; Cadence optimized advanced-package heat and stress 8x faster with cuDSS; COMSOL's multiphysics simulations run up to 10x faster. In manufacturing, Lam Research expects select wafer-etch modeling to run up to 30x faster after integrating the open-source NanoVDB library, and PhysicsNeMo has cut plasma-prediction simulation from days to milliseconds; Applied Materials reports chamber simulations up to 35x faster with Omniverse digital twins. In inspection and test, KLA's new NPP kernel runs 50x faster than earlier CPU versions, Teradyne made probe-maintenance inference roughly 85x faster, and imec improved its lithography process window by 30% using cuLitho.
Why NVIDIA wants to run the fab's brain
These figures deserve a cool head: every one comes from NVIDIA's and its partners' release, most are early or single-benchmark results, real fab gains await production validation, and cuPotential itself is only in early access. The direction, however, is not in doubt. Advanced processes involve thousands of steps, and testing a process change on a live line risks entire wafer batches; letting agents exhaust the simulation space in a digital twin and catch defects earlier is, in effect, added capacity. What NVIDIA is selling is no longer just chips, but the design, simulation, and operations layer of the factories that make chips — from tools that build AI to tools that build the tools. Two things are worth watching next: whether these agentic workflows enter daily decision-making on production lines, and whether the deepening NVIDIA ties of EDA leaders Cadence and Synopsys redraw the simulation software landscape.