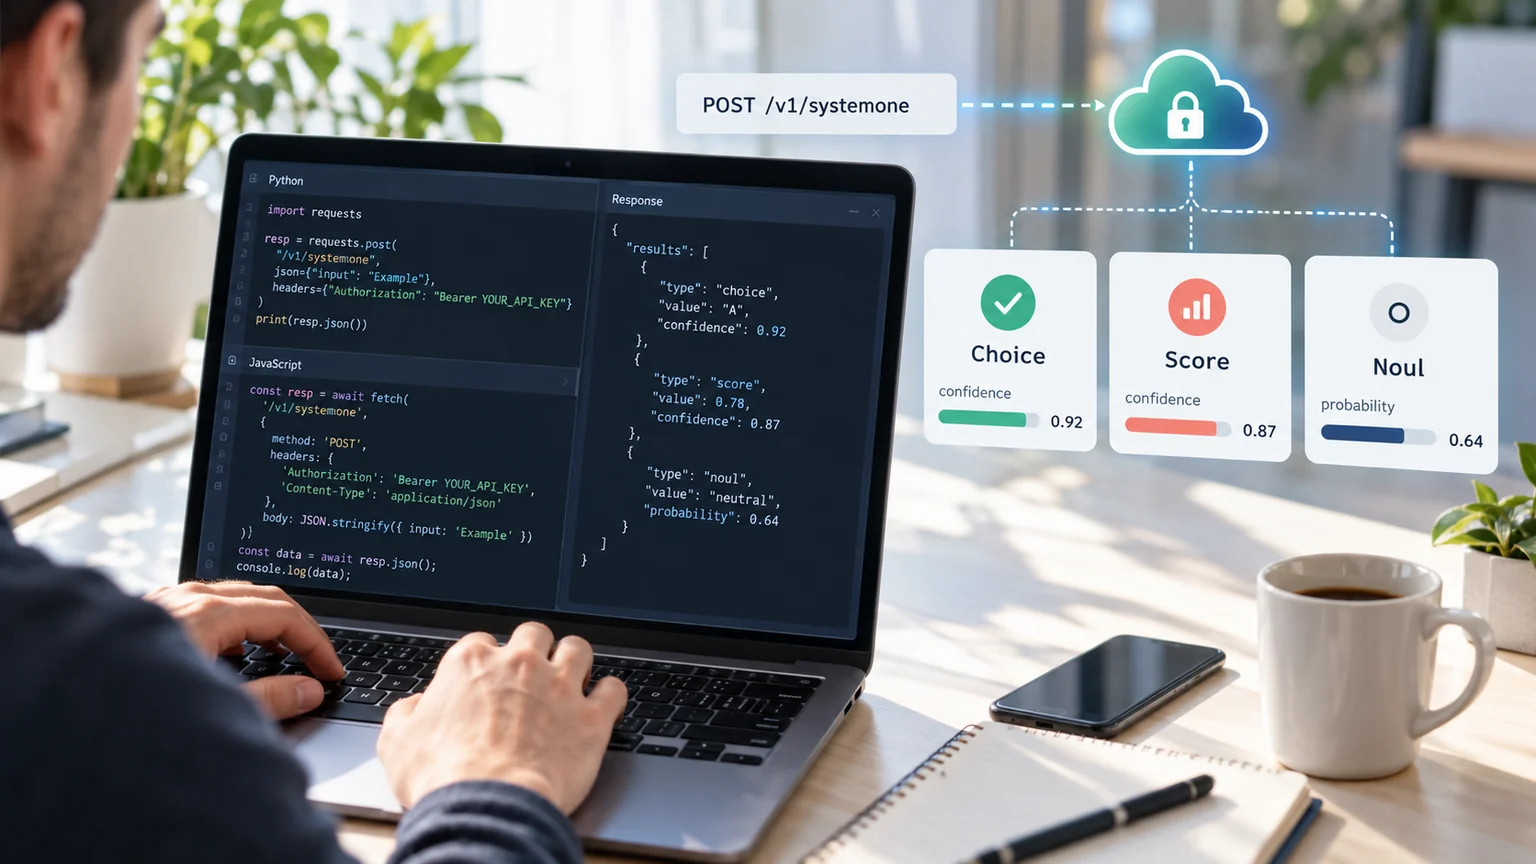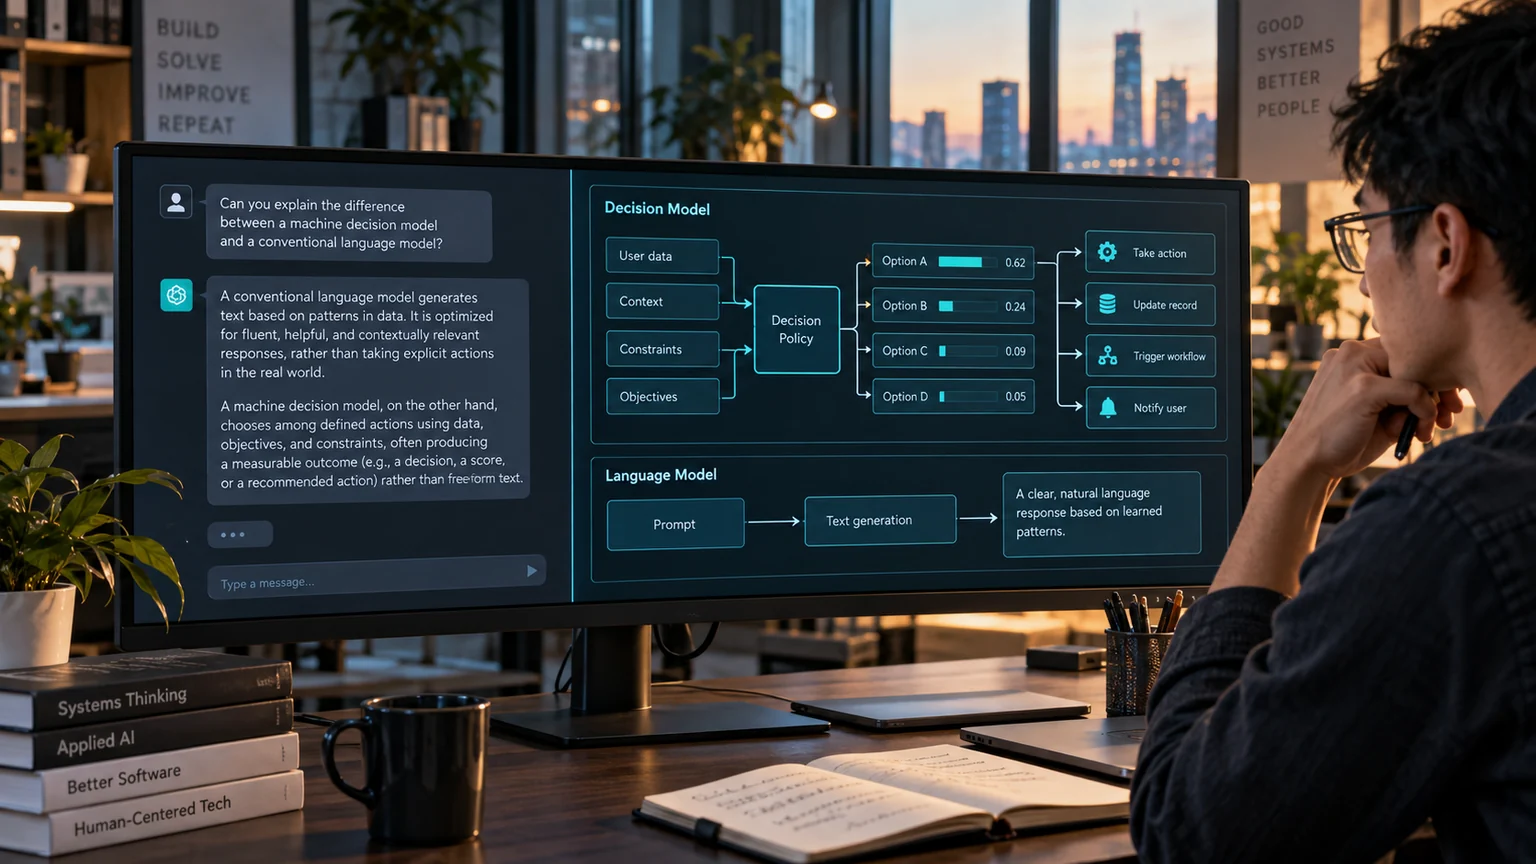
TypeSafe AI is not another chatbot, and Jev is not a general-purpose large model to replace ChatGPT or Claude. It is designed for software automation: programs submit a state and predefined questions, and Jev returns options, scores, or non-probabilistic responses, allowing code to directly branch, sort, or trigger the next step.
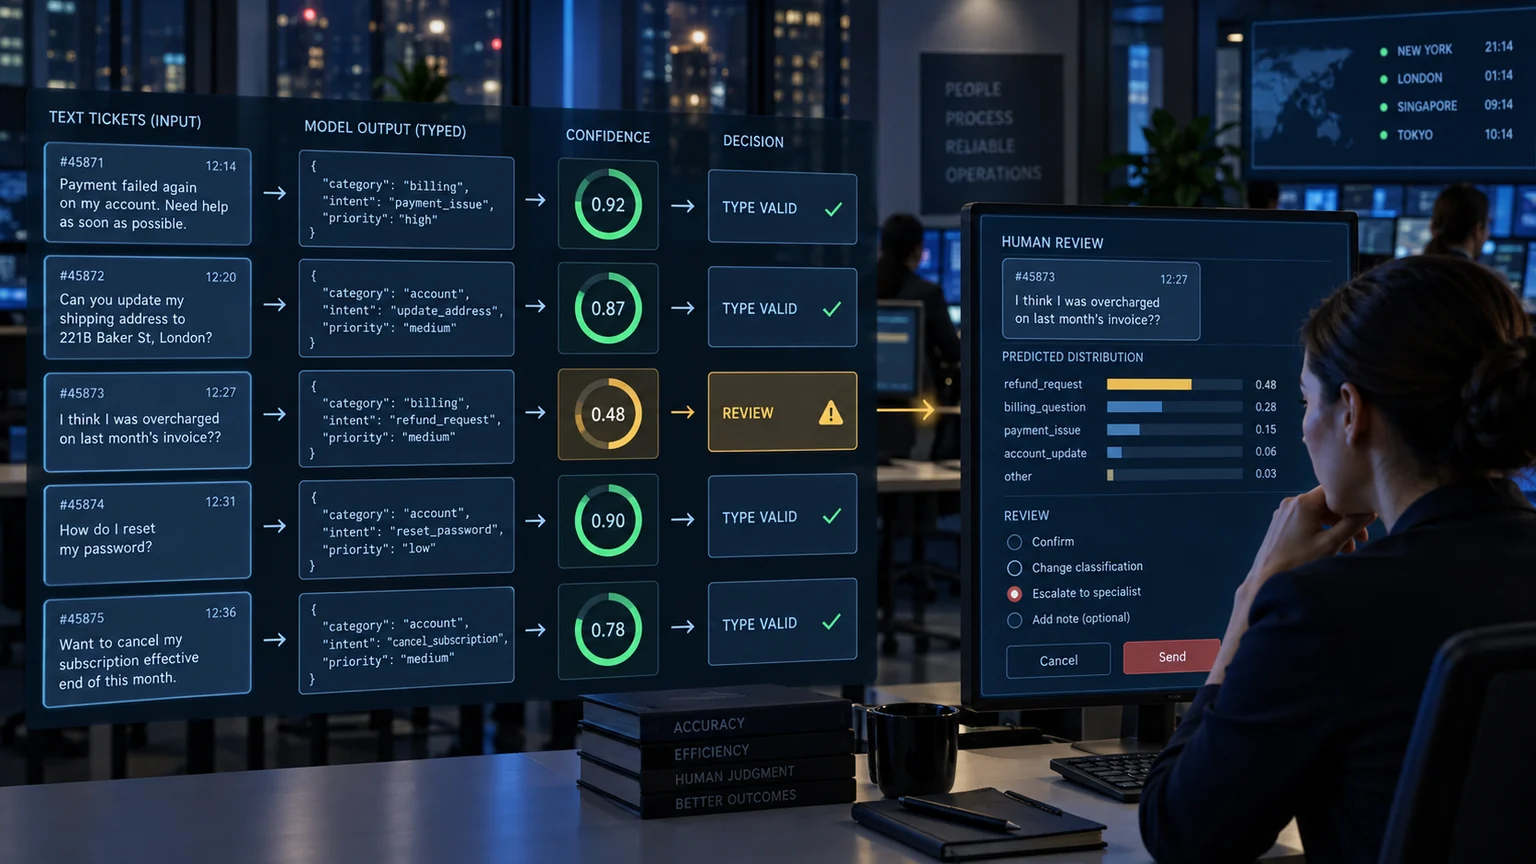
If your needs are to write articles, generate code, or keep chatting, you should continue using generative large models; If your needs are to categorize work orders, assess risks, and sort candidates, and want a fixed output structure, then JEV is the more suitable tool.
The core difference lies in output, not just model size
| Comparison items | Ordinary large models | Jev |
|---|---|---|
| Main damage dealer | Natural language strings | Predefined types of decisions |
| Typical uses | Dialogue, writing, code generation | Classification, scoring, routing, and verification |
| Program access | Usually, analysis and verification are also required | Structured results can be read directly |
| Uncertainty | It may provide confident judgments in writing | Choice and Score return probability distributions and confidence |
TypeSafe calls these models System One Models, emphasizing fast, atomized judgment. Jev receives text or JSON states composed of text, does not generate free text, but makes decisions within the limited answer space you provide.
What do the three problems solve separately?
Choice selects one option from up to 255 options and returns the probability for each option; Suitable for ticket routing and intent classification. Score scores up to 10 sequential levels, suitable for assessing risk, quality, and emotional intensity. Noul answers a true/no question with a probability of "yes," suitable for testing whether a condition holds.
Three types of questions can be executed in parallel in a single request. They share the same state but are independent of each other, and the answer to the previous question does not change the next question.
Which real-life scenarios is it suitable for?
The most suitable steps are those where the answer set is known but rules are hard to fully write, such as assigning customer service messages to billing or technical teams, screening RAG fragments for relevance, determining whether references support claims, and deciding whether the agent calls a skill. The code is still responsible for calculating amounts, checking permissions, and final business actions; Jev only handles the parts that require semantic judgment.
When not to choose JEV
When you need long-form generation, complex multi-step reasoning, precise counting, date calculations, or understanding images or audio, you shouldn't rigidly apply JEV. The official explanation for JEV 1.13 also recommends keeping math and date comparisons in the code and leaving the generation task to the generative model. The criteria are simple: can the answer be defined in advance as a limited option or level? If not, JEV is most likely not the main model.