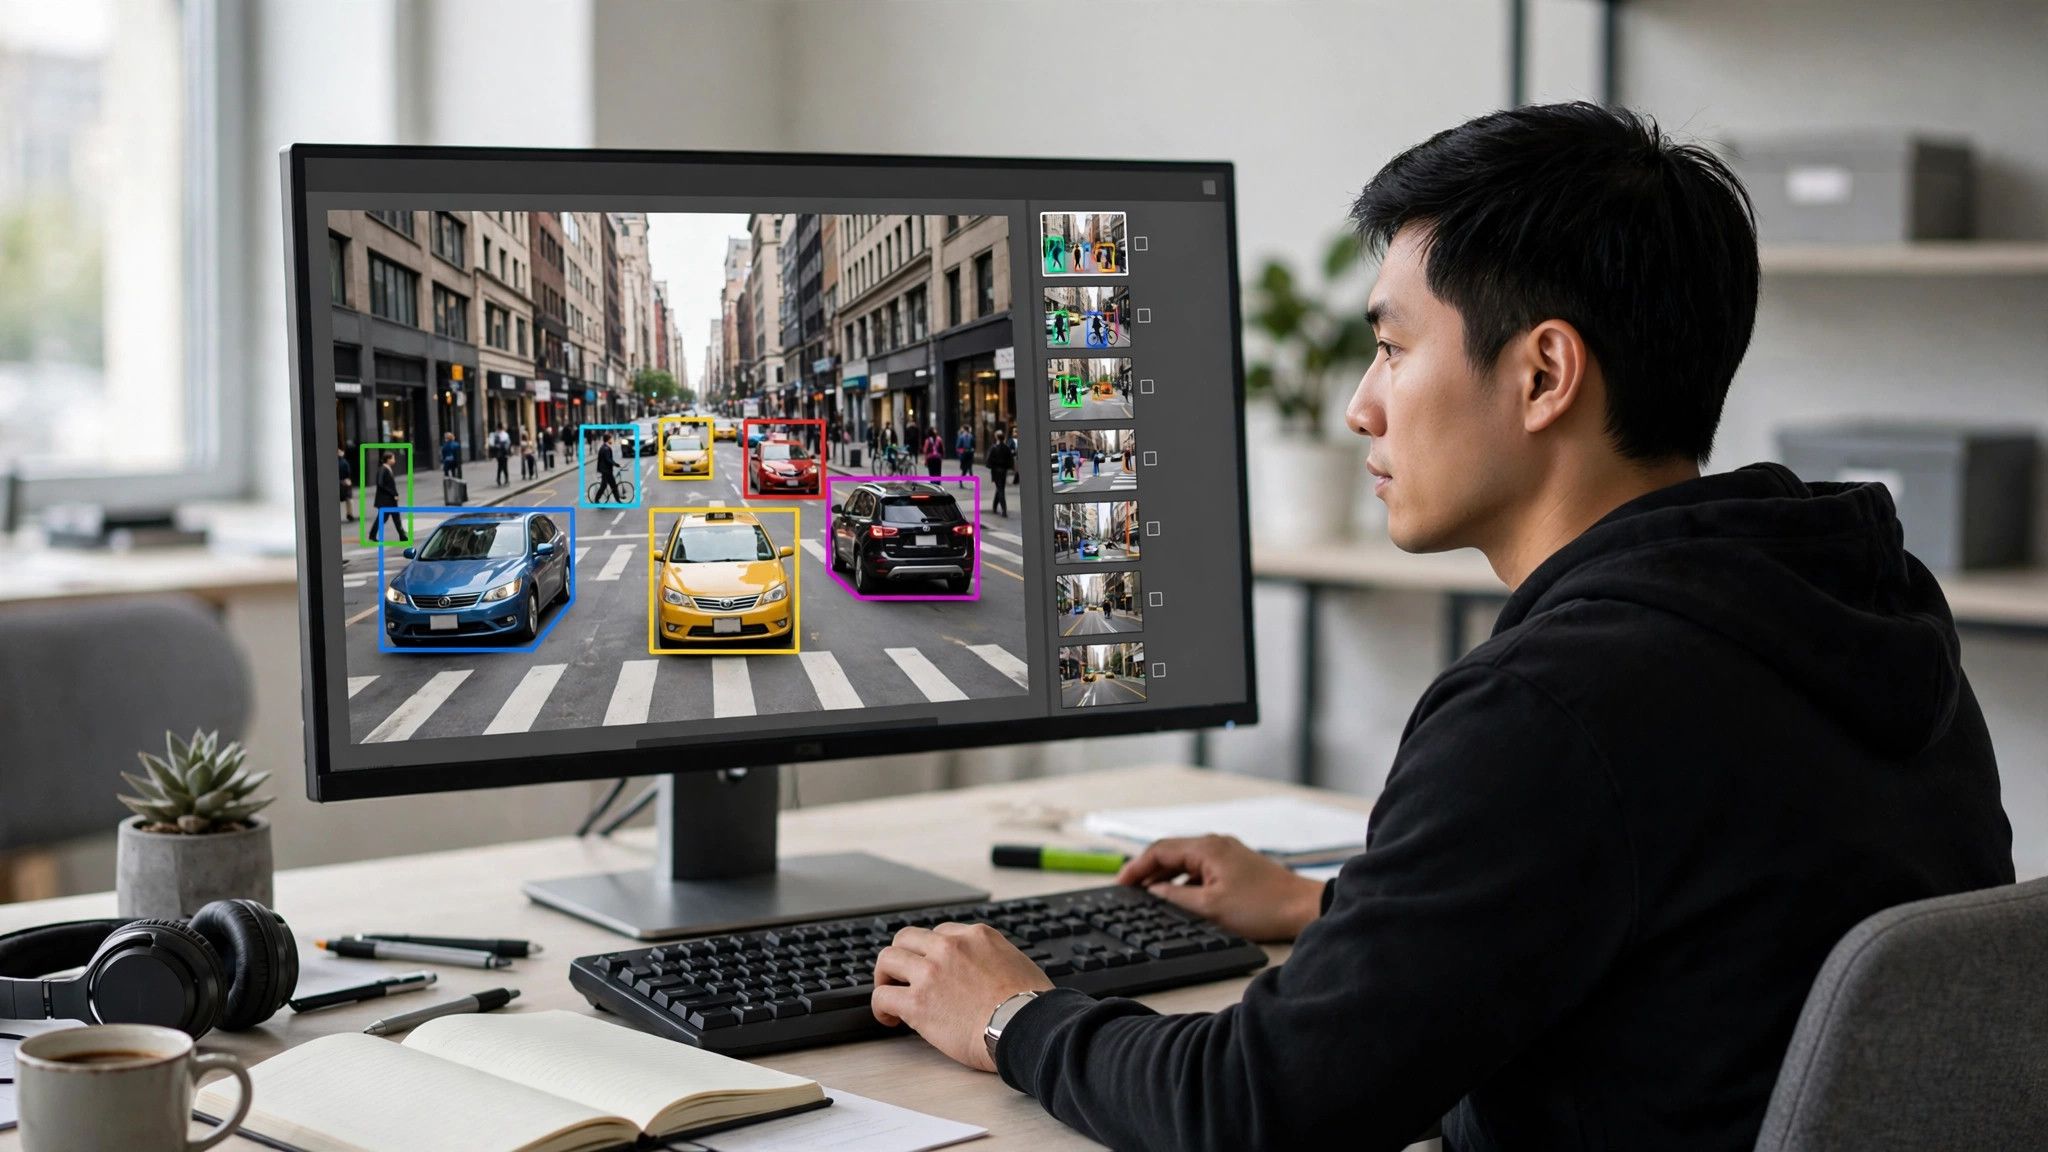
Data annotation is the work of turning raw material into training material with answers attached: a review gets tagged positive or negative, the cars and pedestrians in a street photo are boxed one by one, and two AI replies are ranked by which one is better. What a model studies over and over during training is exactly these labelled examples, and the judgement it learns is, to a large extent, a copy of the annotators' judgement.
What actually gets labelled: five common kinds of work
The first is classification: tagging a whole item, such as whether an email is spam or whether a news story belongs to finance or sport. The second is boxing and segmentation, marking where targets sit inside an image; the vehicle, lane and pedestrian boxes in self-driving training data are produced this way. The third is transcription and alignment, turning recordings into text while noting who said what and from which second. The fourth is extraction, pulling amounts, dates and party names out of a contract into separate fields. The fifth is preference ranking: instead of writing a reference answer, annotators are shown two model replies and pick the more helpful, more honest one — a key material for aligning chat models with human preferences late in training.
How a batch of annotations is produced
The process usually starts with a guideline document: what counts as a positive review, which class sarcasm falls into, how tight a box must hug its target — all written as executable rules with positive and negative examples. A trial round follows, where several people label the same small sample independently, the biggest disagreements are discussed, and the guidelines are revised before volume production. During production, consistency checks are interleaved: the same samples go to different annotators, and if disagreement runs too high the whole batch is reworked; samples nobody can settle go to a more experienced arbitrator. The real cost of annotation is therefore never clicking speed, but this whole quality-control apparatus of guidelines, training, sampling checks and arbitration.
Two frequent misunderstandings
The first is treating annotation as leaking exam answers to the model. Training labels and evaluation answer keys are two different sets: one is the textbook, the other a sealed exam paper. If evaluation data slips into training, scores inflate spuriously, which the field treats as an accident, not a shortcut. The second is assuming automated labelling makes humans unnecessary. Using an existing model to label new data is fast, but it copies the model's own systematic errors into the dataset, neatly and at scale. The common arrangement is machine labelling first, with humans spot-checking low-confidence and high-risk samples; people move into inspection and arbitration rather than leaving entirely.
Why it is closer to ordinary users than it looks
You may never label data yourself, but you keep meeting its downstream effects: fine-tuning an industry model runs on annotated Q&A pairs; the credibility of a model leaderboard depends on how cleanly its evaluation set was annotated; and in safety alignment, which replies should be refused and which refusals are over-cautious are boundaries humans first mark out before they enter training. When a vendor advertises curated data and expert annotation, the three questions worth asking are whether the guidelines are public, how consistency is verified, and who arbitrates disputes. If none of these can be answered, the annotation quality is most likely just marketing language.