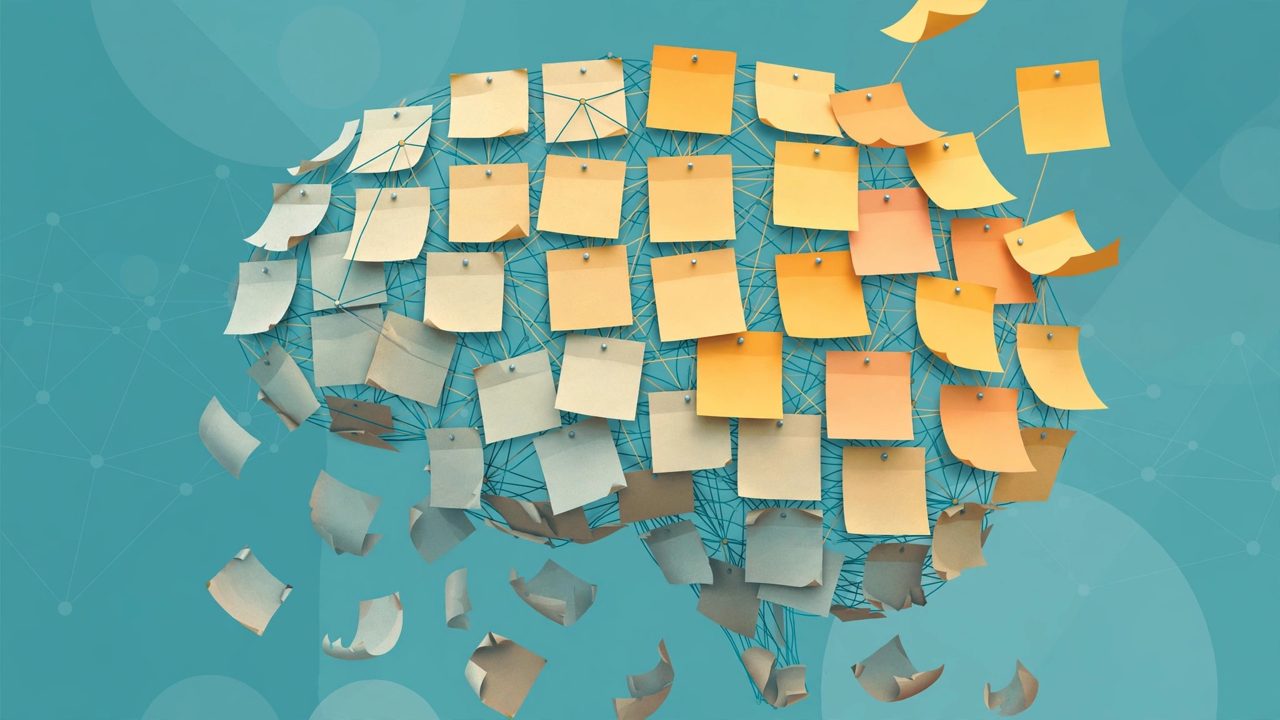
Catastrophic forgetting is what happens when a neural network learns tasks one after another and, in mastering the later ones, loses much of what it had learned before. Fine-tune a capable model on data from a new domain and the new task scores climb, while question answering, classification or a language it used to handle well quietly gets worse. Many teams hit this on their first incremental training run. The model has not become stupid; the training method itself carries this side effect.
Why new data washes old parameters away
A model's abilities are not stored in a separate warehouse for each task. They are spread across one shared set of parameters. During continued training the objective only measures error on the new data, so gradients push parameters toward whatever helps the new task, and nothing defends the old positions. The more the tasks overlap in parameters, the longer the run and the larger the learning rate, the more of the old skill gets rewritten. Picture one whiteboard reused for every lesson with no reserved area for earlier notes: what gets erased is not a corner but whole sections.
Boundaries with two look-alike situations
The first is ordinary poor generalization: failing on unseen problems was never a learned skill in the first place, so it is not forgetting. The test is strict. The same old task, answered correctly before the new training and wrongly after it, with the drop caused by that training, is catastrophic forgetting. The second is human forgetting, which is usually gradual and can be repaired by review and association. Neural forgetting can be abrupt: a single training round can push a task's accuracy close to random, which is why it earned the word catastrophic.
Where it bites most often
Feed a support model new product Q&A over time and it may slowly get worse at older products. Train heavily in a second language after the first and the first language's nuance erodes. Retrain a robot or driving model on a new city's sensor data and its judgment in the old environment can wash out. The shared pattern is sequential data scored only against the current batch. Train on everything mixed together at once and the effect is usually far milder, which is why pretraining rarely raises it and incremental fine-tuning and continual learning raise it constantly.
Remedies, each covering part of the road
Replay is the simplest and most common move: mix some old-task samples into the new data, like reviewing old lessons while learning new ones, at the cost of storing old data and extra compute. Regularization approaches lock the parameters that mattered most for old tasks and penalize changing them, elastic weight consolidation being the classic idea. Isolation approaches give new tasks their own space, training only a small set of added parameters, low-rank adapters or separate modules, so the base barely moves. In practice teams combine them: a small learning rate, replayed samples, adapter-only training, plus a fixed regression set of old tasks checked after every update.
Forgetting is not simply the enemy
A point often missed: some forgetting is useful. Old data contains outdated wording, wrong labels and retired business rules, and a model that refuses to let go of any of it cannot absorb the new. What needs preventing is uncontrolled forgetting, where an important skill is washed away silently and without a check. The key engineering habit is therefore not to demand zero forgetting, but to rerun a fixed old-task test set after every incremental update and ship only when the drop stays within bounds you chose in advance.