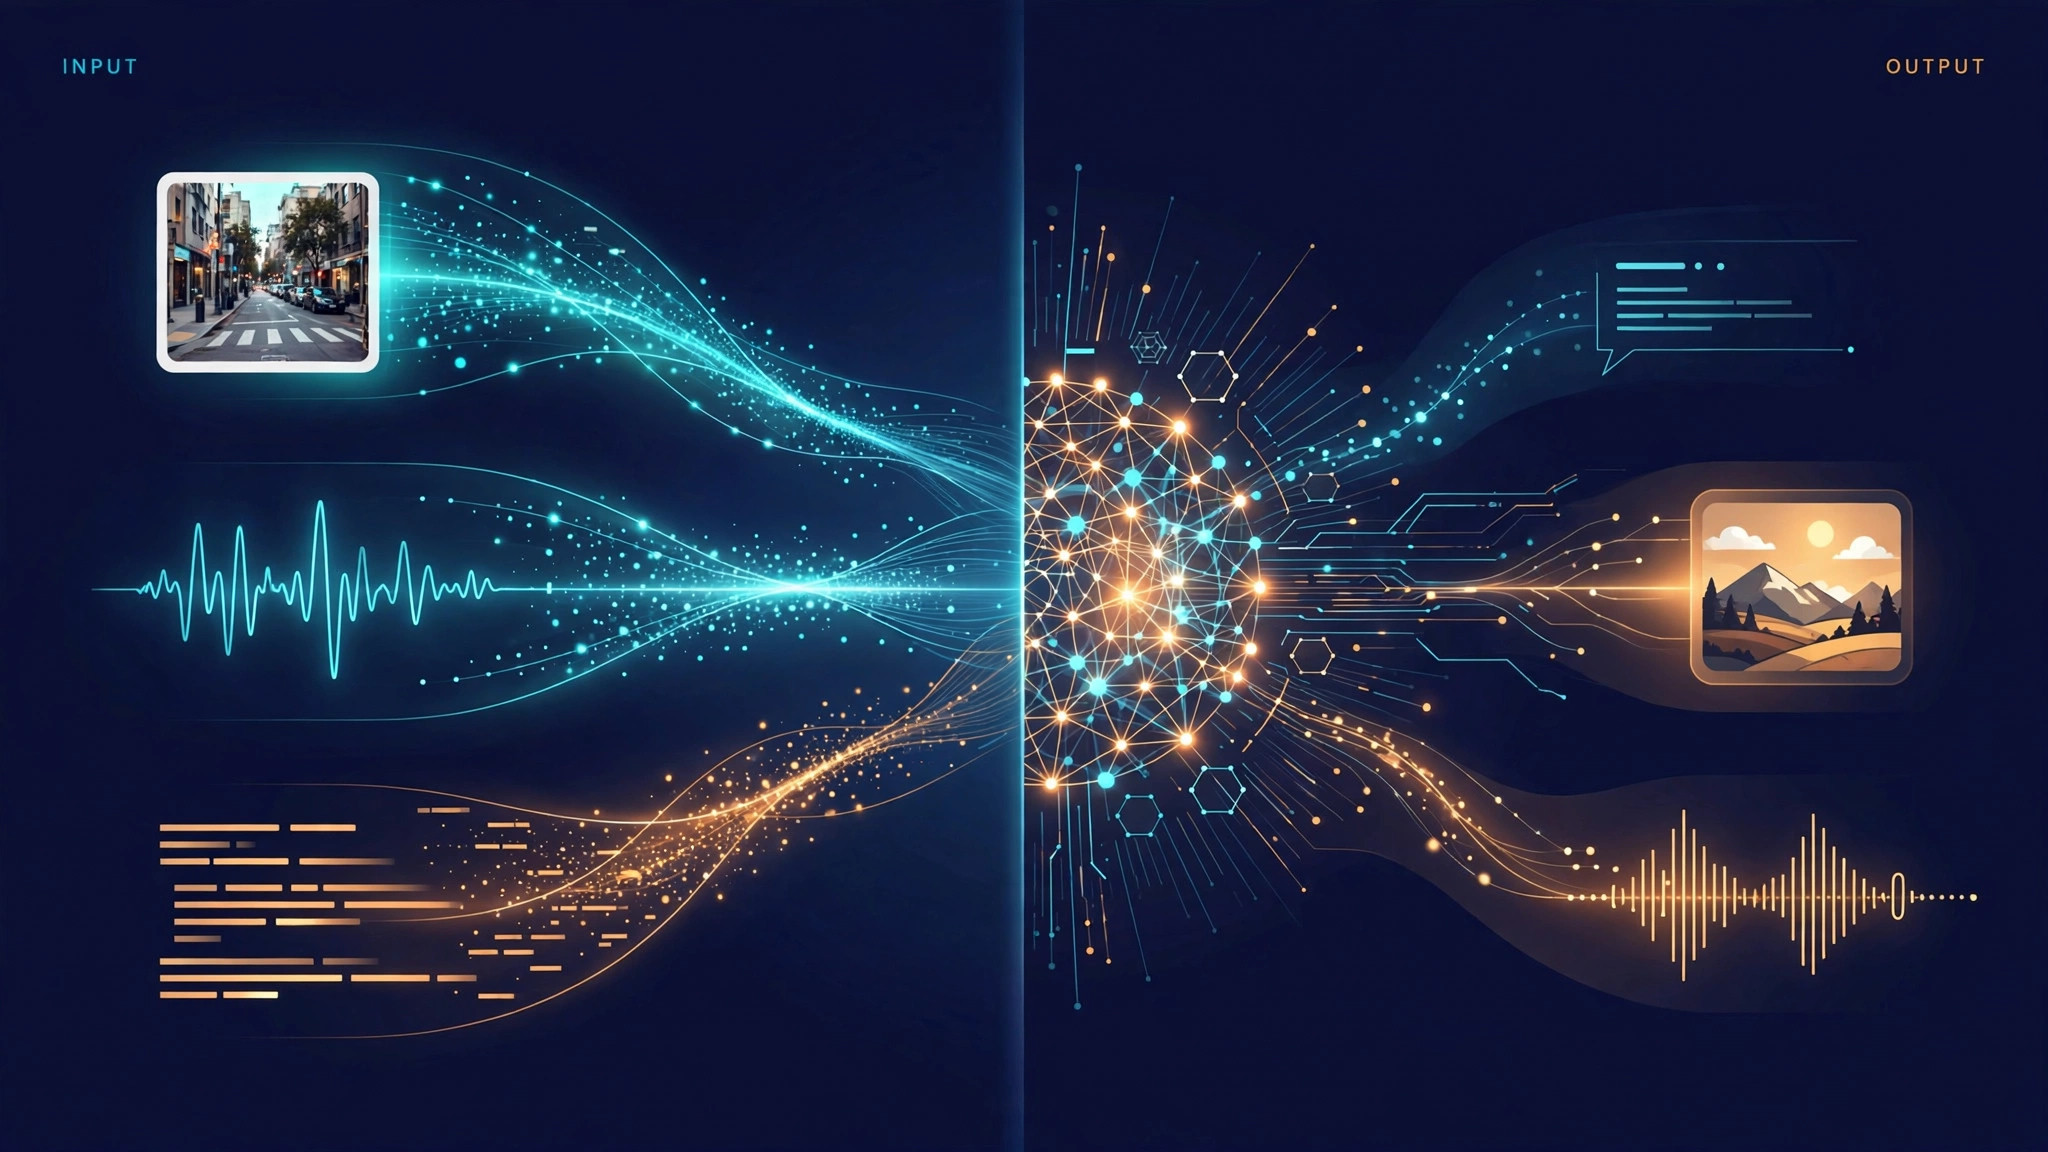
A multimodal model is an AI model that can process multiple forms of information — text, images, audio — at the same time: hand it a picture, a voice clip, or a few lines of text, and it can take them in together and respond. But let's draw the boundary first: "multimodal" does not mean "omnipotent." It simply has more input and output channels; it hasn't automatically gained human-like understanding. It can describe how many people are in a photo and what they're doing, yet fail to tell who's joking.
Three common forms: understanding, generation, and unified models
The three types are easy to tell apart, yet mixing them up is the source of many misconceptions. Understanding-oriented models use text as the "brain" with "eyes and ears" bolted on — GPT-4o is a typical example: images and audio are first encoded into features, then reasoned over together with text. Their strength is visual Q&A; their weakness is that fine detail gets lost along the way. Generation-oriented models work the other way around — text in, other modalities out — like DALL-E and TTS voice models: great at creating "something from nothing," but weak at understanding. Unified models try to handle all modalities natively in a single model; they're the hardest to train, and truly mature products are still rare. Simply put: understanding models "see with comprehension," generative ones "draw and speak," and unified ones want "it all."
What it can't do
First, fine-grained perception: counting exactly how many beans are in a picture or reading tiny text in a dense table — models routinely miscount or miss things. Second, causality and intent: it can describe "two people arguing," but why they're arguing can only be guessed from common sense. Third, expert judgment: reading X-rays or engineering drawings gets only "looks like" answers — fine as an assistant, not as the final word. Fourth, it never admits what it "didn't see clearly": faced with a blurry image, it would rather invent a plausible-sounding answer. Cross-checking is essential for consequential judgments.
Three concepts people mix up
Cross-modal retrieval (e.g., searching images with text) does "matching" — mapping text and images into the same space to find the closest hit. It only "finds"; it doesn't "think." A multimodal model does "reasoning" — answering and judging on the basis of understanding. One finds, the other thinks. Many tools claim they "can see images" but merely pipe pictures through OCR or a captioning API into a text-only model. This "pipeline stitching" falls apart on questions needing joint visual-textual reasoning — ask "what's funny about this meme" and it can only restate what's visible, missing the joke. In a true multimodal model, visual information participates in the unified reasoning process.
Two widespread misconceptions
Seeing does not equal understanding: a model's ability to describe images comes from the massive image-text pairs seen in training — essentially pattern matching. It can say "there's a cat on the sofa" because it's seen ten thousand similar pictures, not because it truly understands cats. With humor, sarcasm, or cultural references, its "understanding" is often just a lucky guess. More modalities does not mean a stronger model: each added modality adds training difficulty, and a mid-sized model honed on image-text tasks will often beat a jack-of-all-trades giant. Judge by benchmarks and real-world testing, not by counting input types.
When to use it — and when not to
There's only one test: does the question require "understanding two or more kinds of information at once" to answer well? If yes, use it: photographing a manual to ask "what does this step mean," having it read charts and summarize trends, voice customer service, describing surroundings for visually impaired users — it eliminates the middle step of "first translate the picture into words yourself." If no, don't waste it: plain-text chats are cheaper on a text-only model; high-precision work like medical image screening or industrial inspection is beyond a general model's "rough look"; and when you only need to "find" images rather than "understand" them, cross-modal retrieval is faster.
FAQ
Q: What's the relationship between multimodal models and large language models?
A: Large language models are the foundation: at the core of mainstream multimodal models sits an LLM doing the "thinking," with vision and speech encoders bolted on for "seeing" and "hearing."
Q: Does uploading photos to a multimodal model leak my privacy?
A: Yes. Uploaded images go to the provider's servers, and some services may even use them for further training. Don't upload ID documents, medical records, or private photos directly. If you must, redact them first and turn off options like "use my data to improve the model."