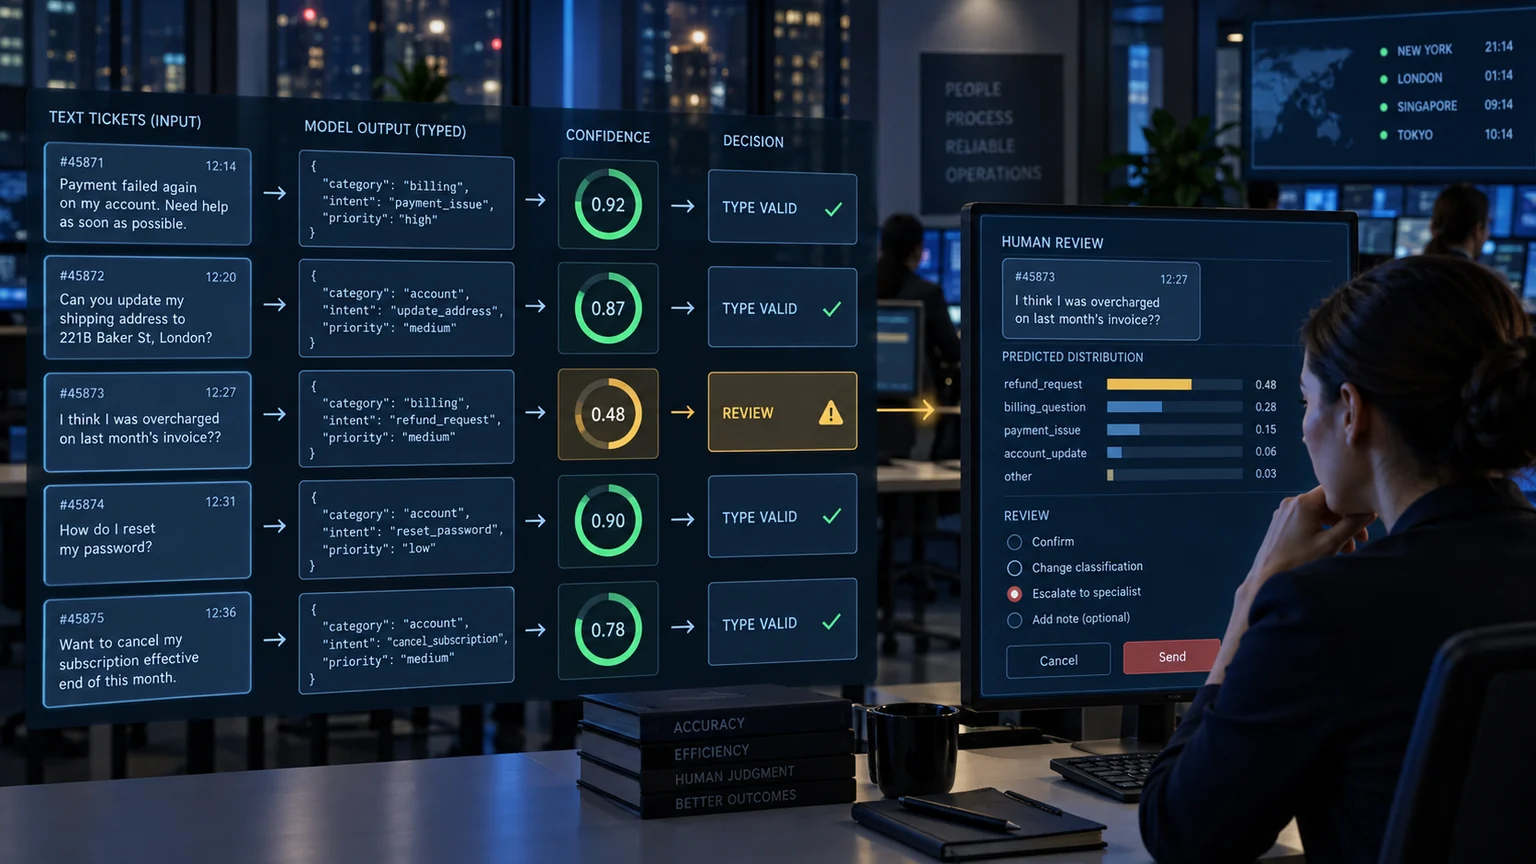
The "zero hallucination" TypeSafe AI refers to the fact that Jev does not return content outside the predefined type, which does not mean every business judgment is 100% correct. Choice does not create option 256 out of thin air, and Score does not return an invalid rating, but it may still select the wrong option among legitimate options. When launching, risk must be controlled using probability, confidence, test sets, and manual review.
What can be guaranteed?
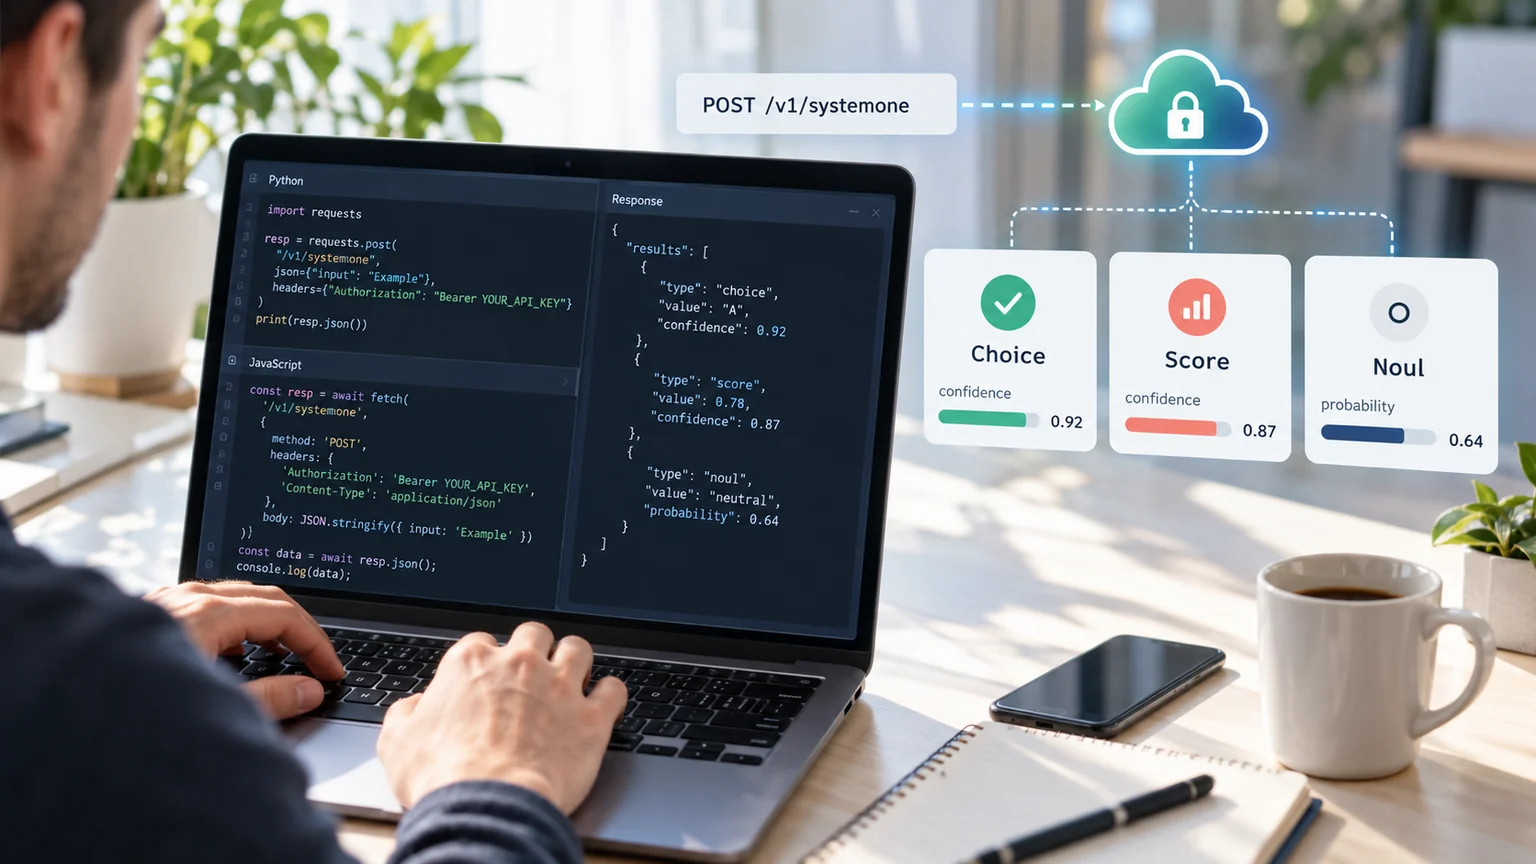
Jev's answer space is predefined by requests, so programs don't have to worry about suddenly receiving an unresolved chat, fictitious tool name, or error field type. The official description of "typeless errors" is a structural guarantee, solving common parsing failures and out-of-bounds output issues in automated systems.
And what is it that cannot be guaranteed?
The model may still misunderstand ambiguous instructions, ignore indirect relationships, or be distracted by long, irrelevant information. The official weaknesses listed by Jev 1.13 include precise counting, mathematics, date comparison, complex indirect reasoning, adversarial content, and conflict standards. Correct structure, correct facts, and correct judgment are three different things.
| The result | Whether the type is legal | Determine reliability |
|---|---|---|
| Return billing from billing and technical | Legal | It still depends on the content of the news and the probability |
| Returns undefined legal_team | Illegal | The type constraint of JEV will block it |
| Automatic refunds are still available when confidence is low | Exports can be legal | Business strategies are insecure |
How should confidence be used?
Choice and Score return probability distributions and provide confidence from 0 to 1; Noul directly returns the probability of "yes" without additional confidence. There is no universal answer to the threshold; it should be set based on the cost of misjudgment: content recommendations can be relatively lenient, while refunds, bans, and medical diversion should be more conservative.
The system can be designed in three stages: high-confidence automatic execution, intermediate areas sent for manual verification, and low-confidence rejection of automatic action or switching to a safe path. Thresholds must be debugged using real samples and cannot be copied directly from the demo numbers.
Four ways to reduce misjudgment
- Each question expresses only one judgment, and boundary conditions are written into criteria.
- First, filter out irrelevant context, sending only the state needed to make the decision.
- Math, counting, date, and permission rules are handled with deterministic code.
- A fixed model version is established as a regression set, and error distributions and thresholds are compared before upgrading.
So "zero illusion" can be understood as outputs not crossing type boundaries, rather than the model gaining the ability to never make mistakes. Only by writing this boundary into the architecture can TypeSafe truly improve automation reliability.